How it was made
The criteria, six AI-generated designs, two AI scorers, no winner, and a hybrid. Then the limits, a log of who decided what, and what changed.
Contents
This is the design decision.
A design decision is about setting the criteria to evaluate which idea wins.
— the working rule for this studyThree hard gates first. An option that fails one is out, whatever else it scores. Here the agent’s product is the guest, and the console it lands in is the host.
- G1 · The guest never overwrites the host. Status syncs both ways between the two products, and Wiz’s severity can raise an alert’s priority, so one silent write can change two systems at once. Pass or fail, not a degree.
- G2 · Buildable from what the host already lets a guest use. A dashboard widget, a case-wall entry, a playbook result. Anything that needs the host to change its own chrome is solving a different problem.
- G3 · It passes the count on the console page. Every mark the card adds is legible on screen, and it reuses no glyph the host already uses for something else.
Then six weighted criteria, each scored across five dimensions — user impact, failure severity, frequency, strategic alignment, competitive leverage — to earn its weight rather than be assigned one.
| Criterion | Weight | Because |
|---|---|---|
| Found on the view the case opens to | 3× | An unfound verdict plays no part in the decision |
| Confidence that changes the card | 3× | People over-rely on confident-looking automated advice (Parasuraman & Manzey, 2010) |
| Says what it saw, and when | 2× | Alerts can join the case after the analysis ran |
| Accept or override, consequence shown first | 2× | One disposition can change two systems |
| Evidence checkable inside the case | 2× | The conclusion is currently a truncated string |
| Disagreement between the two severities shown | 2× | Nothing on screen reconciles them today |
Proposed at 17 Sep, 18:17 IST, ninety minutes before the first option existed: seven criteria, with a recommendation to cut one. The six were confirmed on 18 Sep, after all six options existed and before either scorer ran. That is a proposal, not pre-registration. The seventh, legible with no admin setup, became a briefed requirement instead, checked and reported.
Five were generated by an agent working from a written brief. The brief is the work; the generation is a method note.
The brief carried the criteria, the three gates, the host’s documented extension points, the synthetic case data and the six states every option had to draw — including the ones nobody enjoys drawing: analysis pending, analysis failed, and no widget installed at all. Each run got the same brief and one difference in how it was seeded. One run was given no direction beyond the rules and the data.
The sixth is Option 0: the original ask made literal — verdict, confidence, evidence, provenance, accept and override — generated by a model, like the other five, before the criteria were applied to anything. It is in the set so the criteria have something unexamined to be measured against.
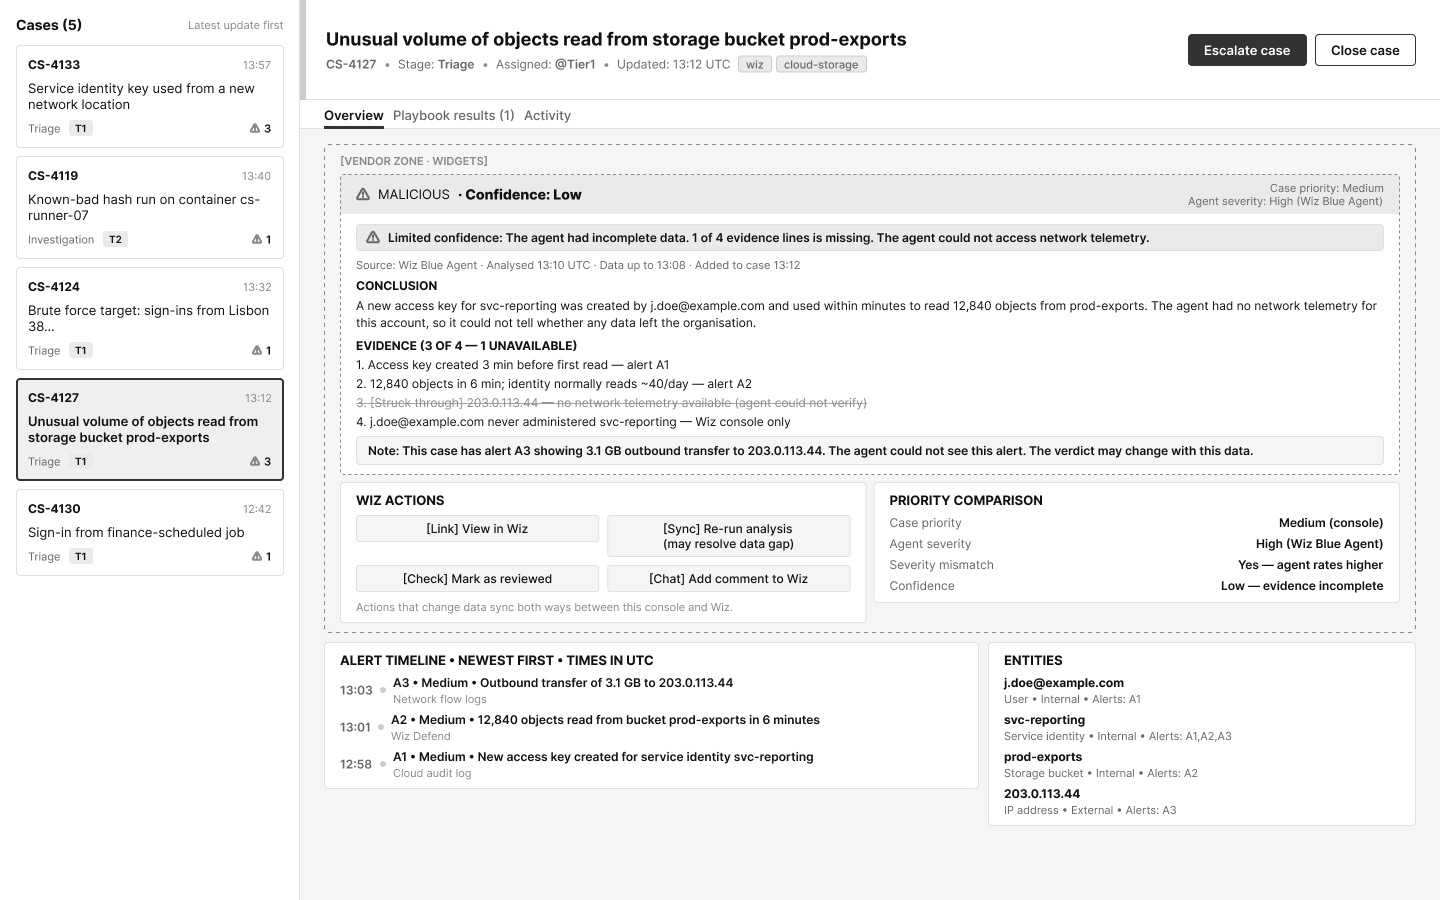
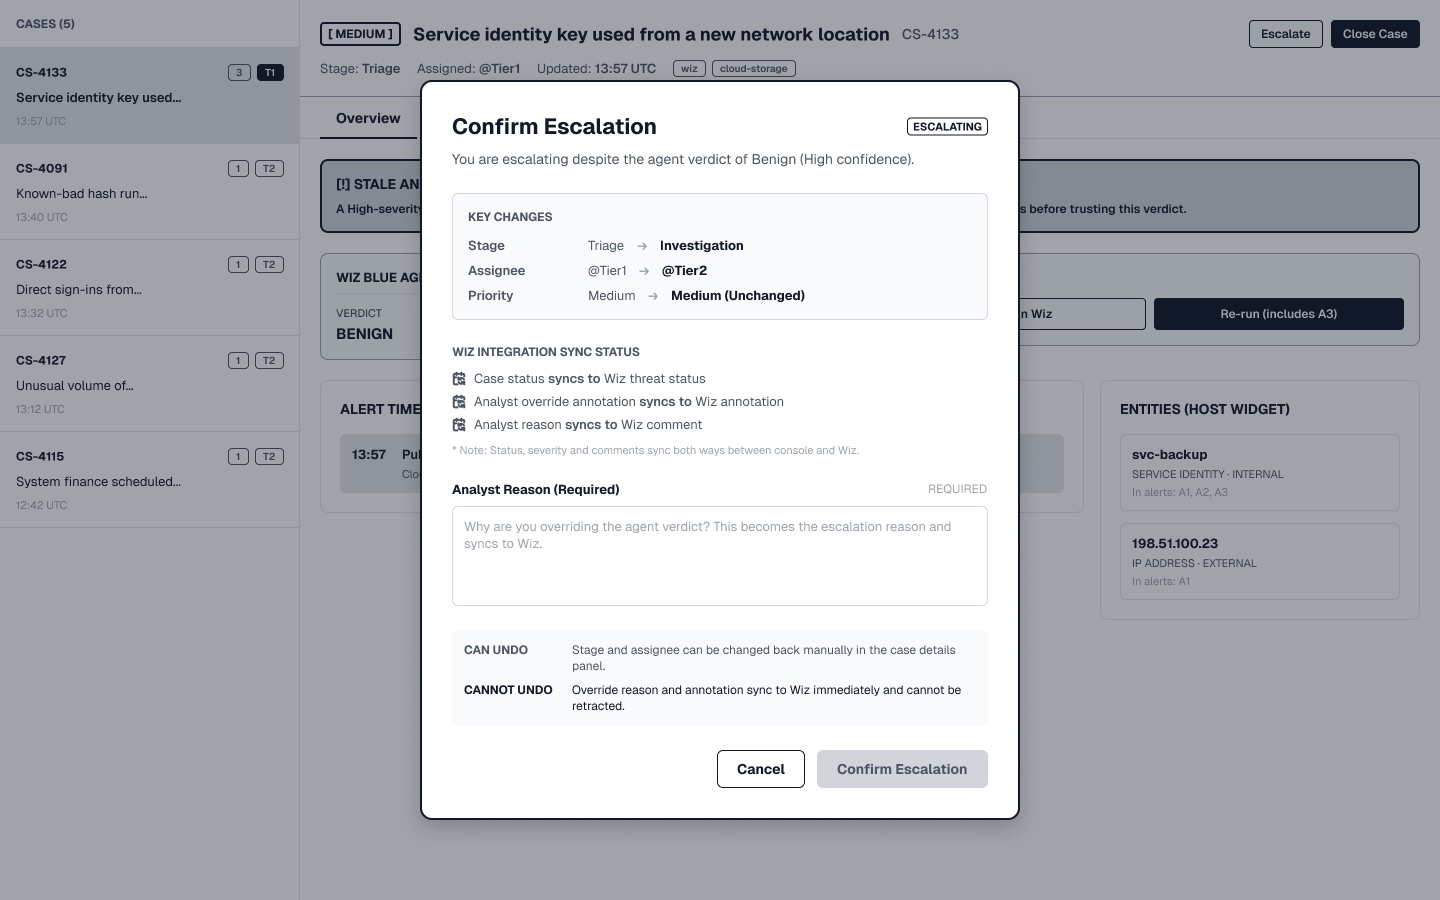
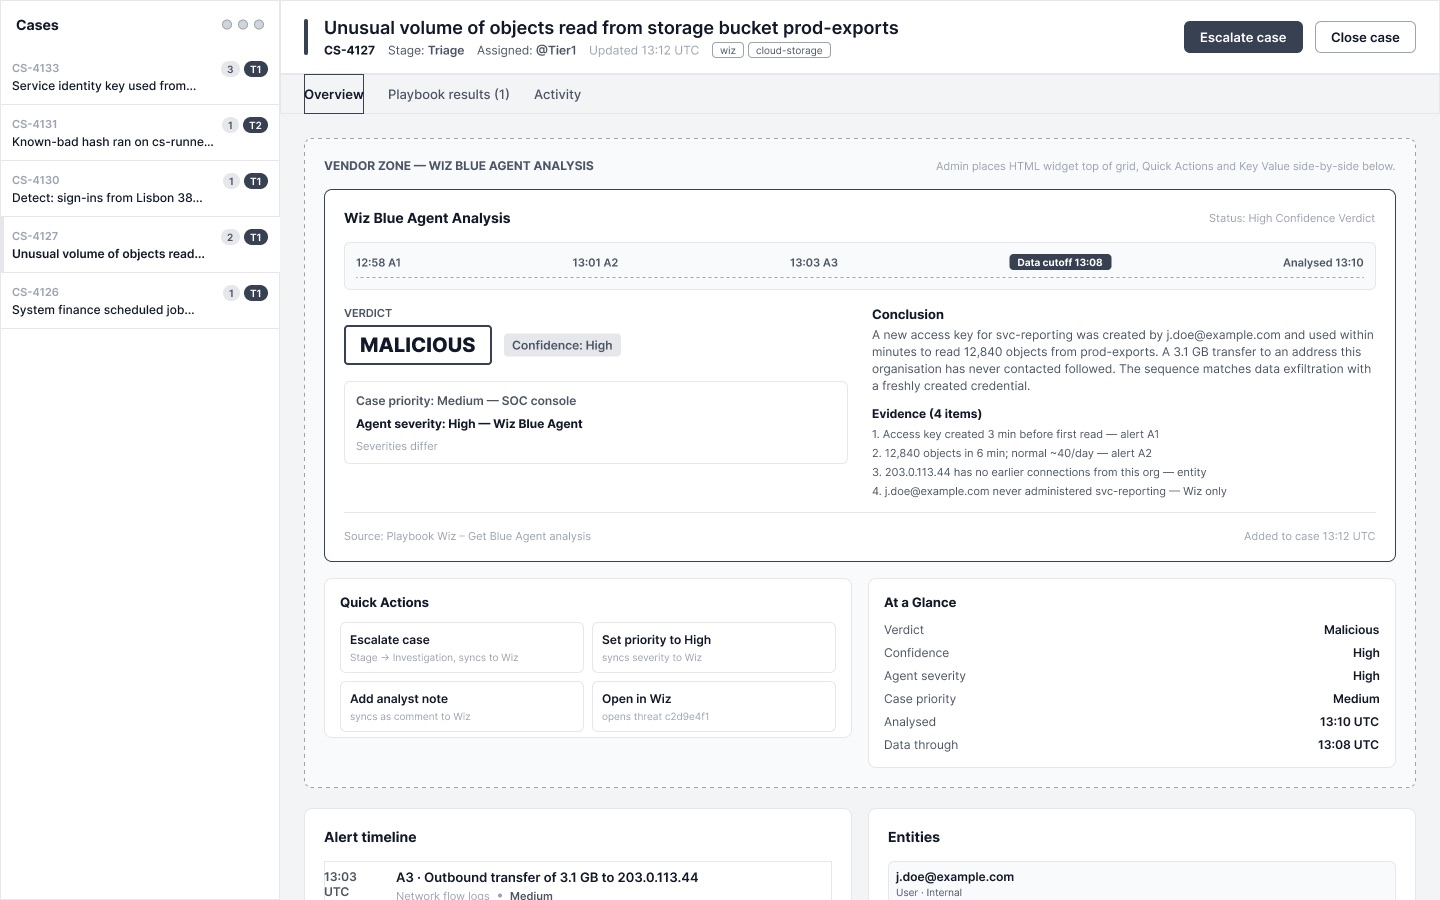
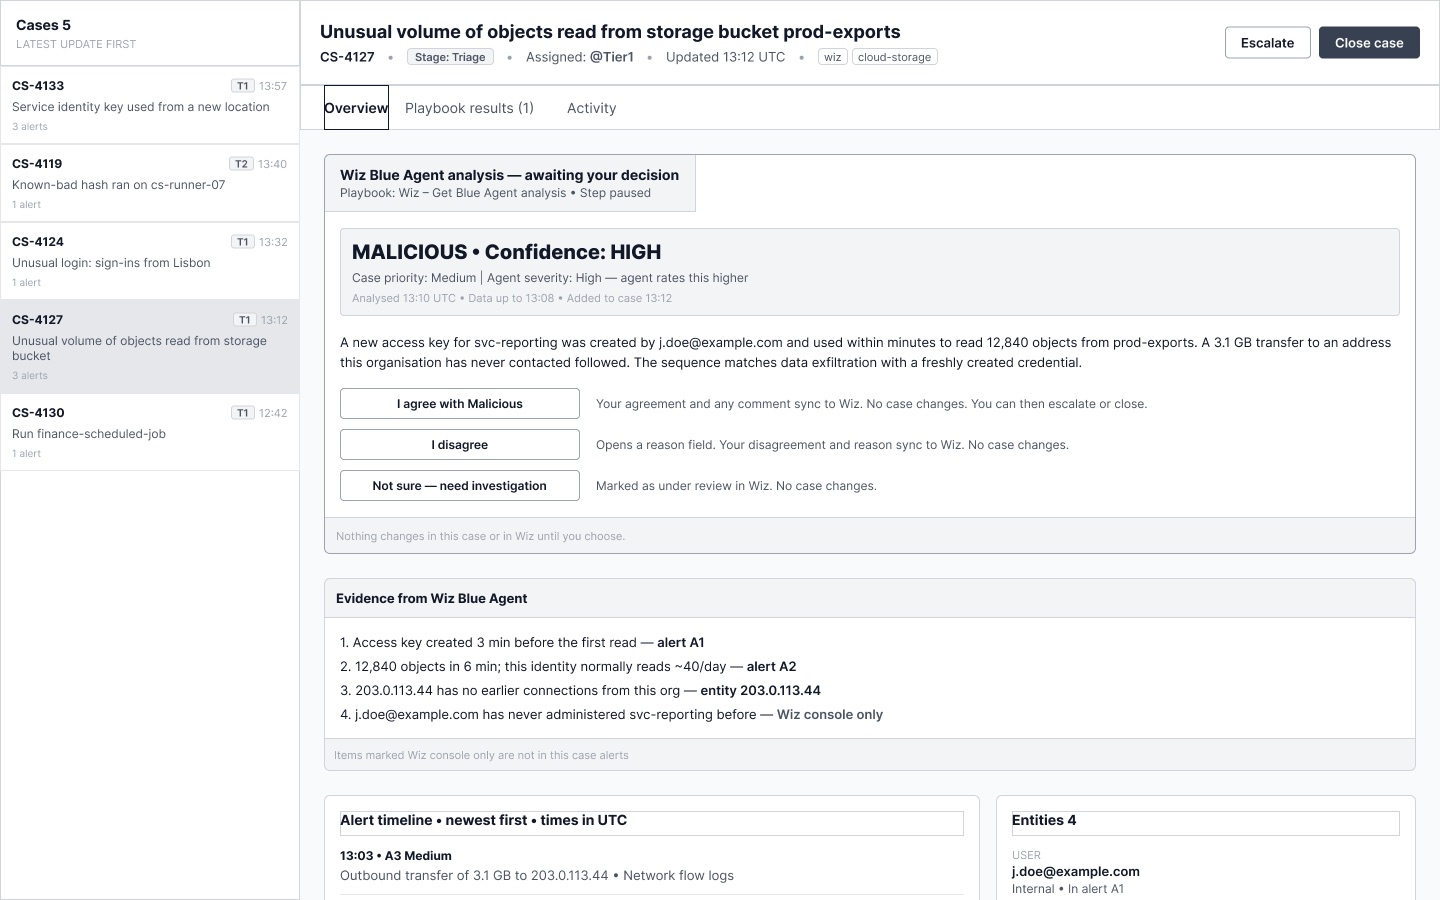
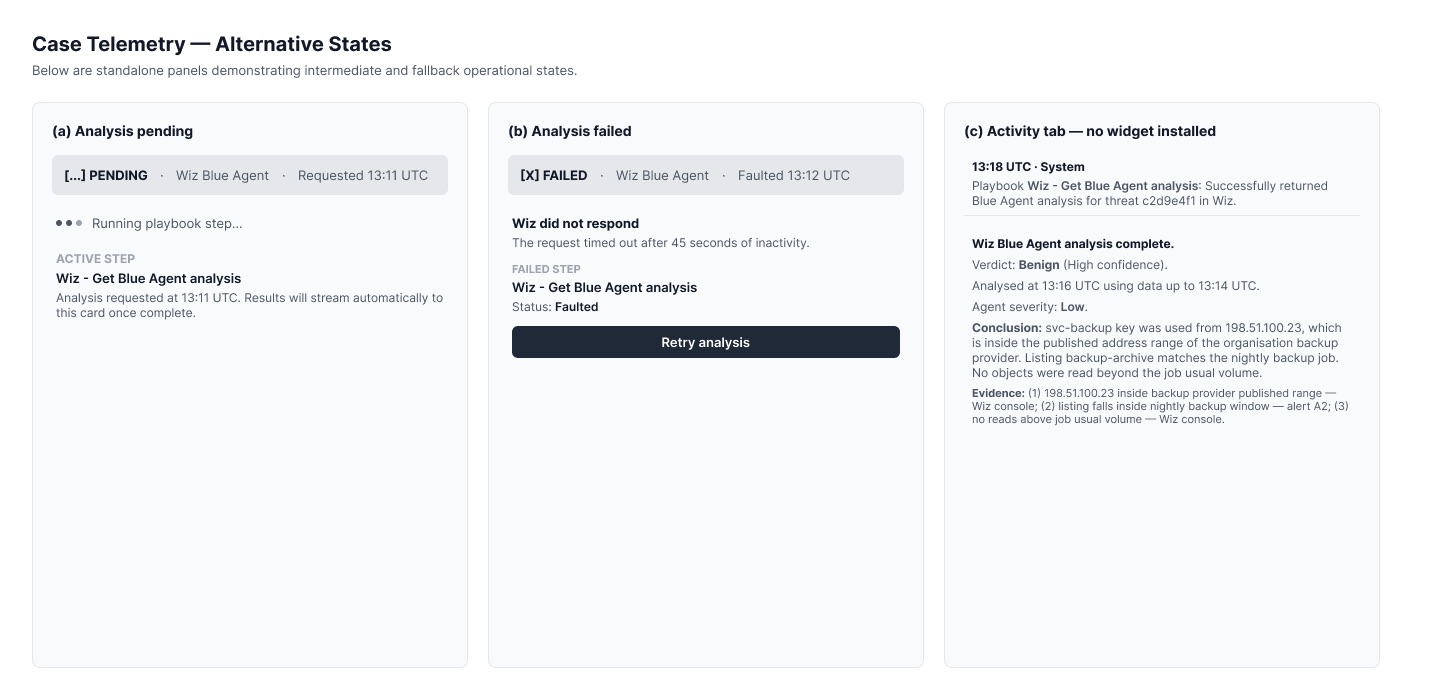
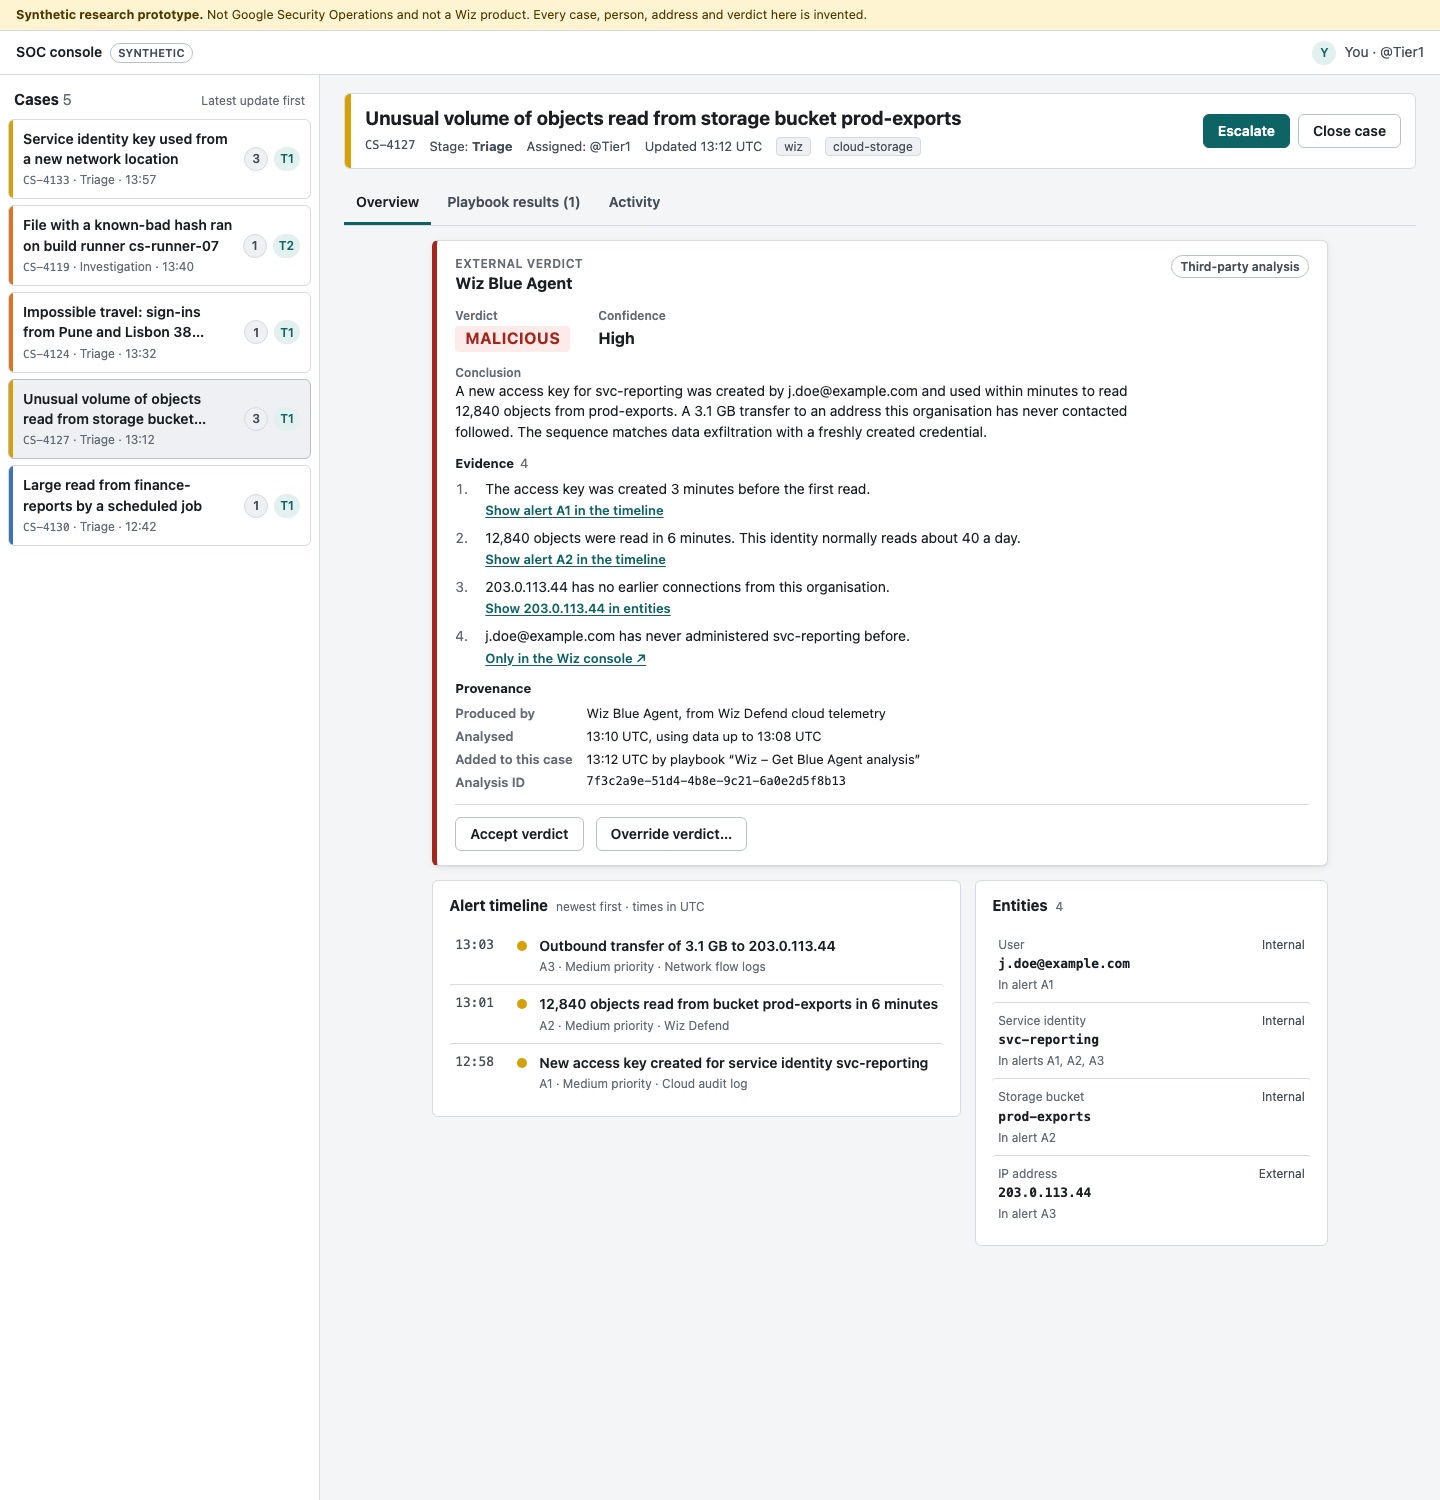
Option 0 runs in the prototype too: open it.
Two AI scorers worked the same rubric independently, and neither could see the other’s notes. They are the same kind of reader, though: a human pass is still missing.
They agree on first place and disagree on second. One AI scorer put R5 5.0 points clear of R3; the other put it 8.6 clear of R2. Neither margin clears the 10-point close-call rule fixed before any option existed, so no winner is declared. R5, the run given no direction at all, leads both passes; the runner-up changes identity between them.
Two findings do more work than the ranking.
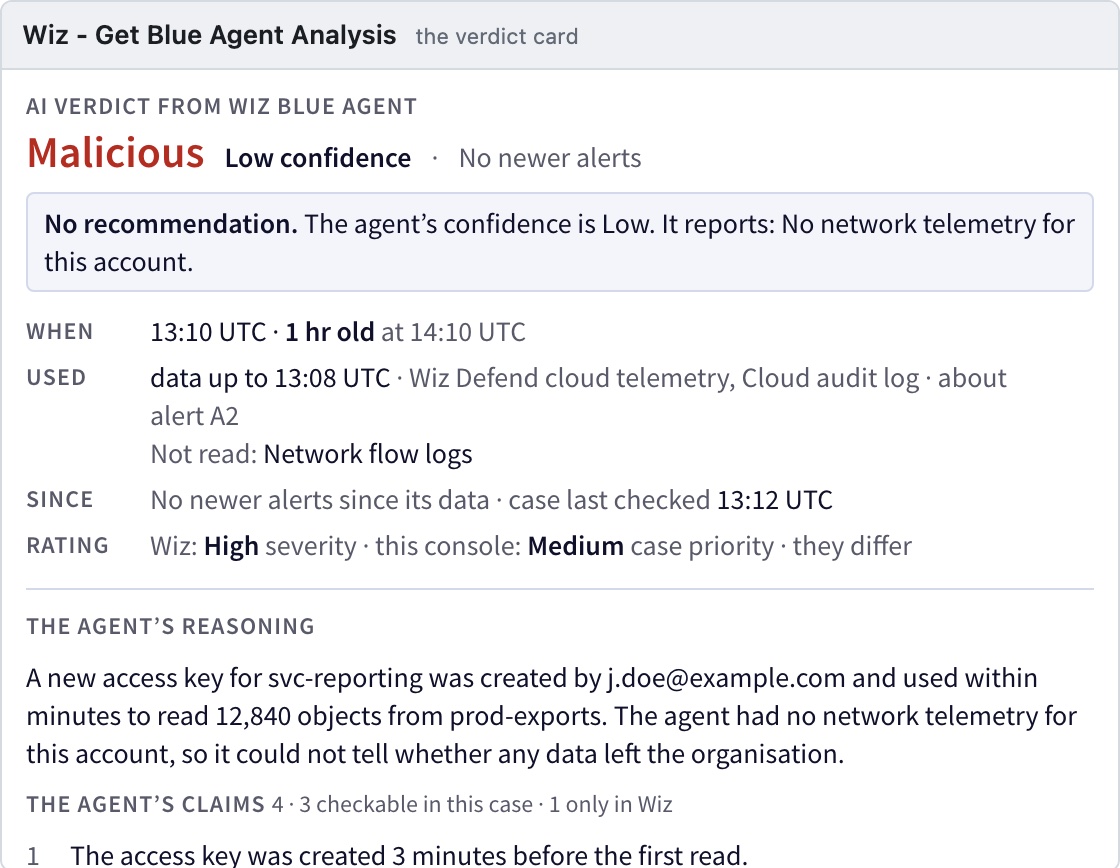
- Both scorers found that low confidence changes what every card says, and little of what it offers. One found that no option restrains the act; R5 only re-aims its re-run at the gap. The other credited R5 alone, for withdrawing its recommendation line.
- The option built literally from the original ask came last in both passes, and it failed two gates. G3, for its bar: it coloured the card’s left edge by verdict, red for Malicious and green for Benign, with no label, where the host already uses a left-edge bar for priority, just above it on the same screen, and in the host’s colours red means Critical. That is the exact class of error the count exists to catch. And G2, for its buttons: it drew Accept and Override inside the card, which an HTML widget cannot do.
What the refusal forced. With no winner, the answer could not be a coronation. It is a hybrid: the parts that scored best, wherever they came from. And three things no option drew, each flagged by the scorers: low confidence withdraws Accept, undo is a control, and the verdict can be revised after the analyst acts. Adding them was my call.
The card, moment by moment, and where each part came from.
| Moment | What the analyst sees |
|---|---|
| The verdict lands | The agent, what it read, when it stopped reading, which alert it is about, and both severities with the system that issued each |
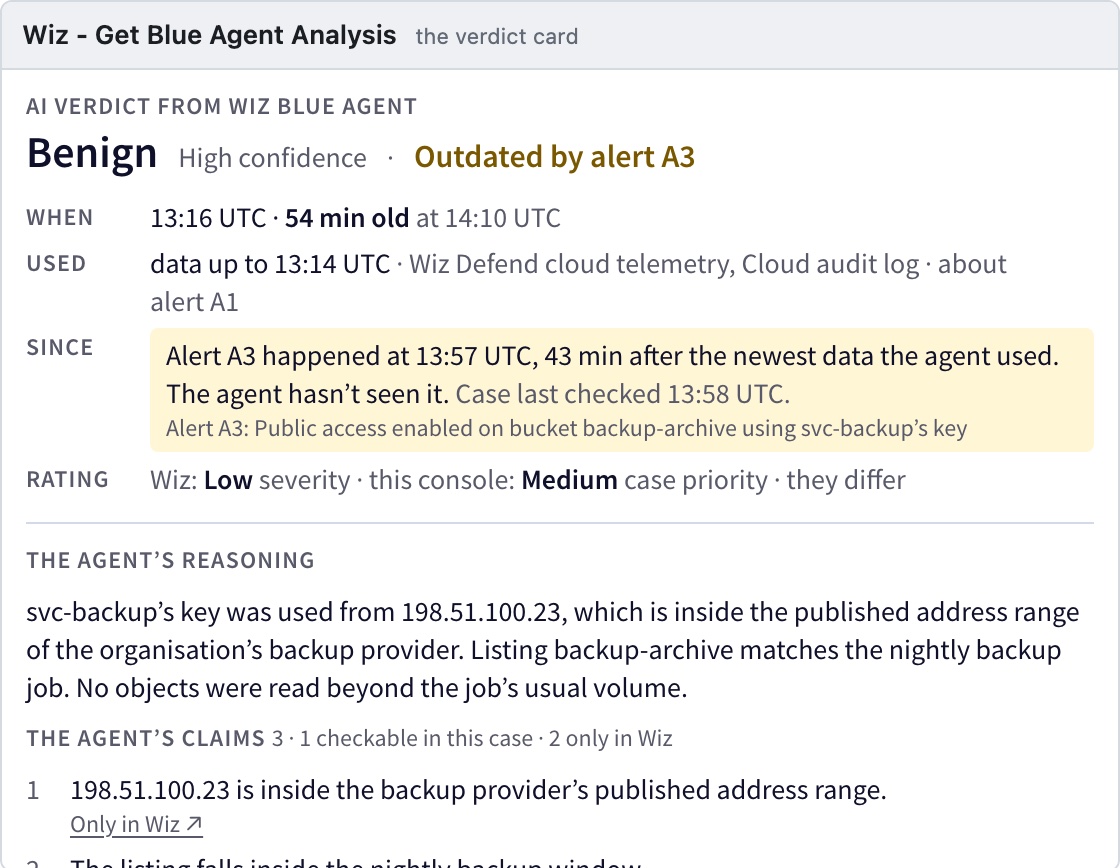
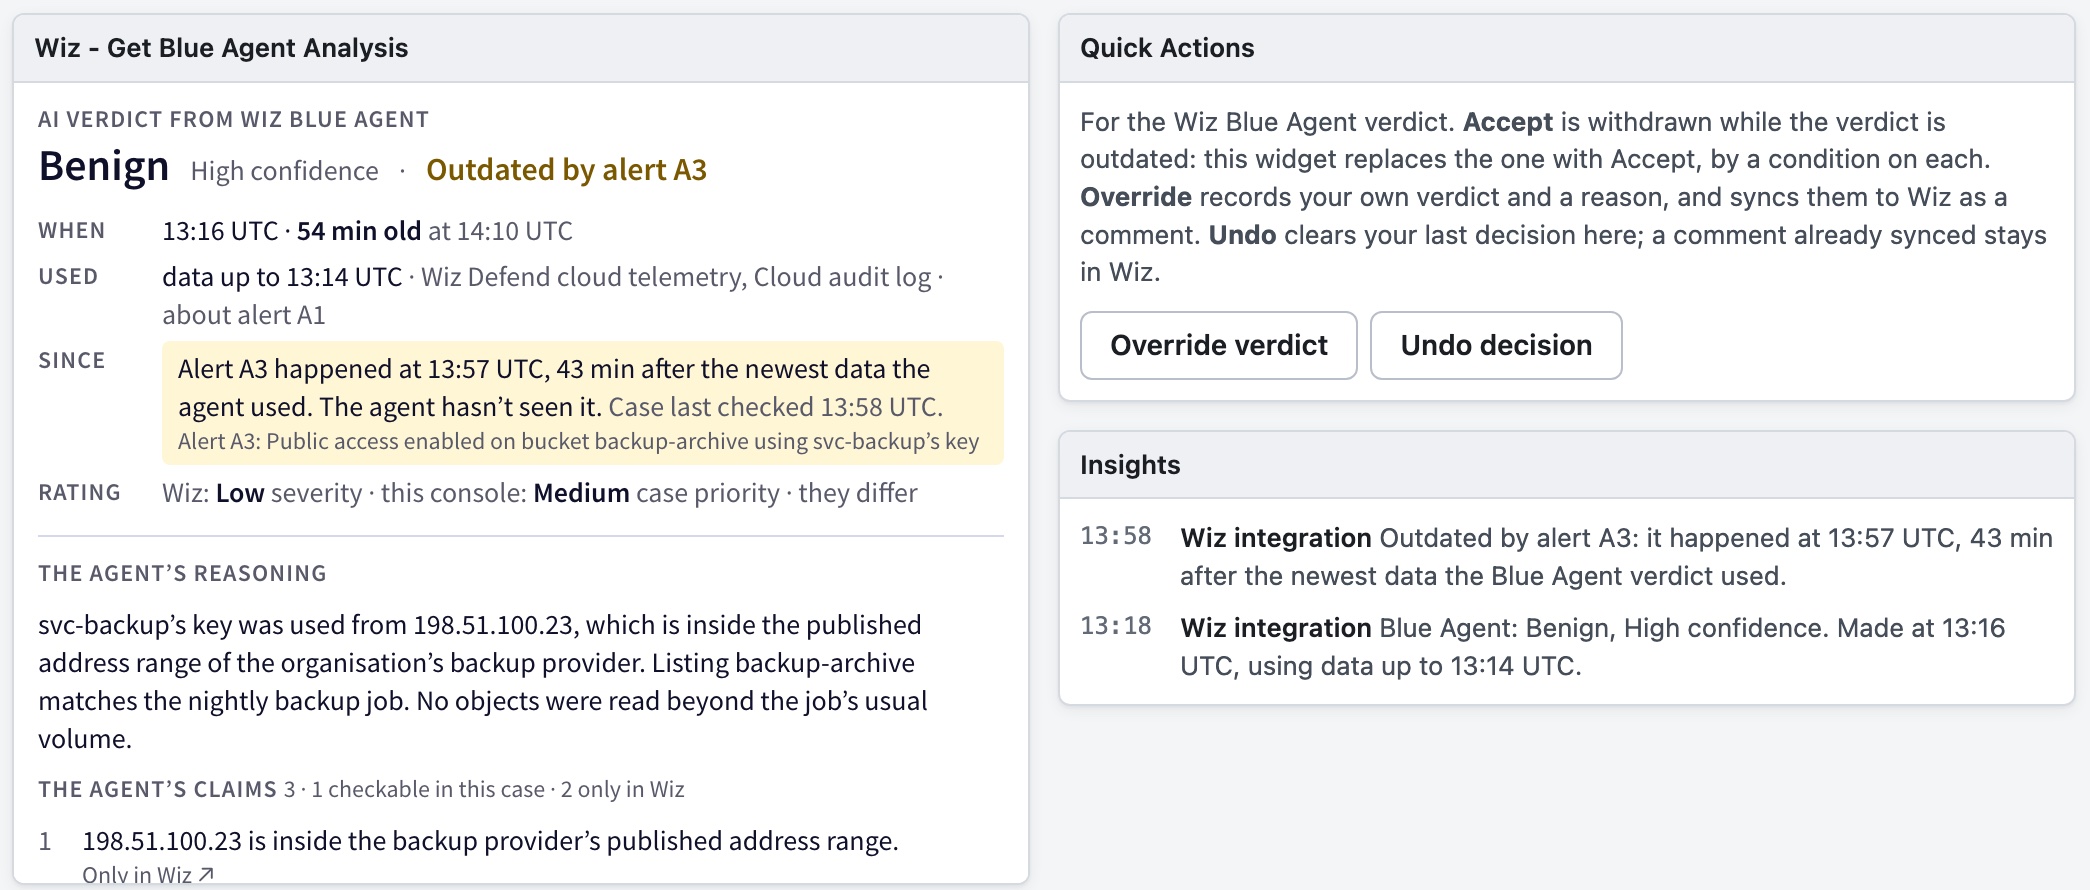
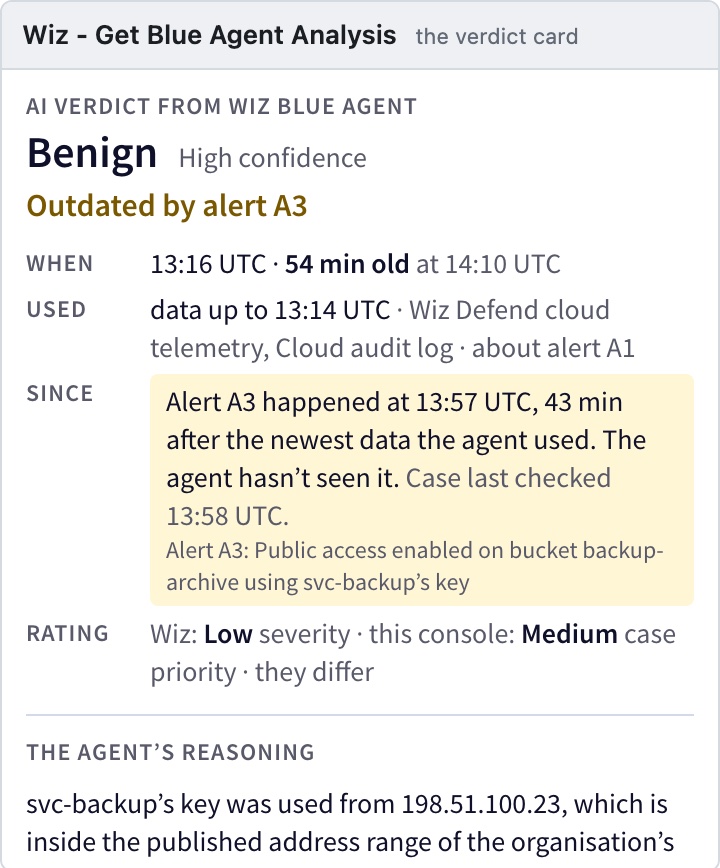
| A newer alert joins the case | “Outdated by alert A3” beside the verdict, then why: “Alert A3 happened at 13:57 UTC, 43 min after the newest data the agent used. The agent hasn’t seen it.” The alert is named, so the analyst can find it in the case |
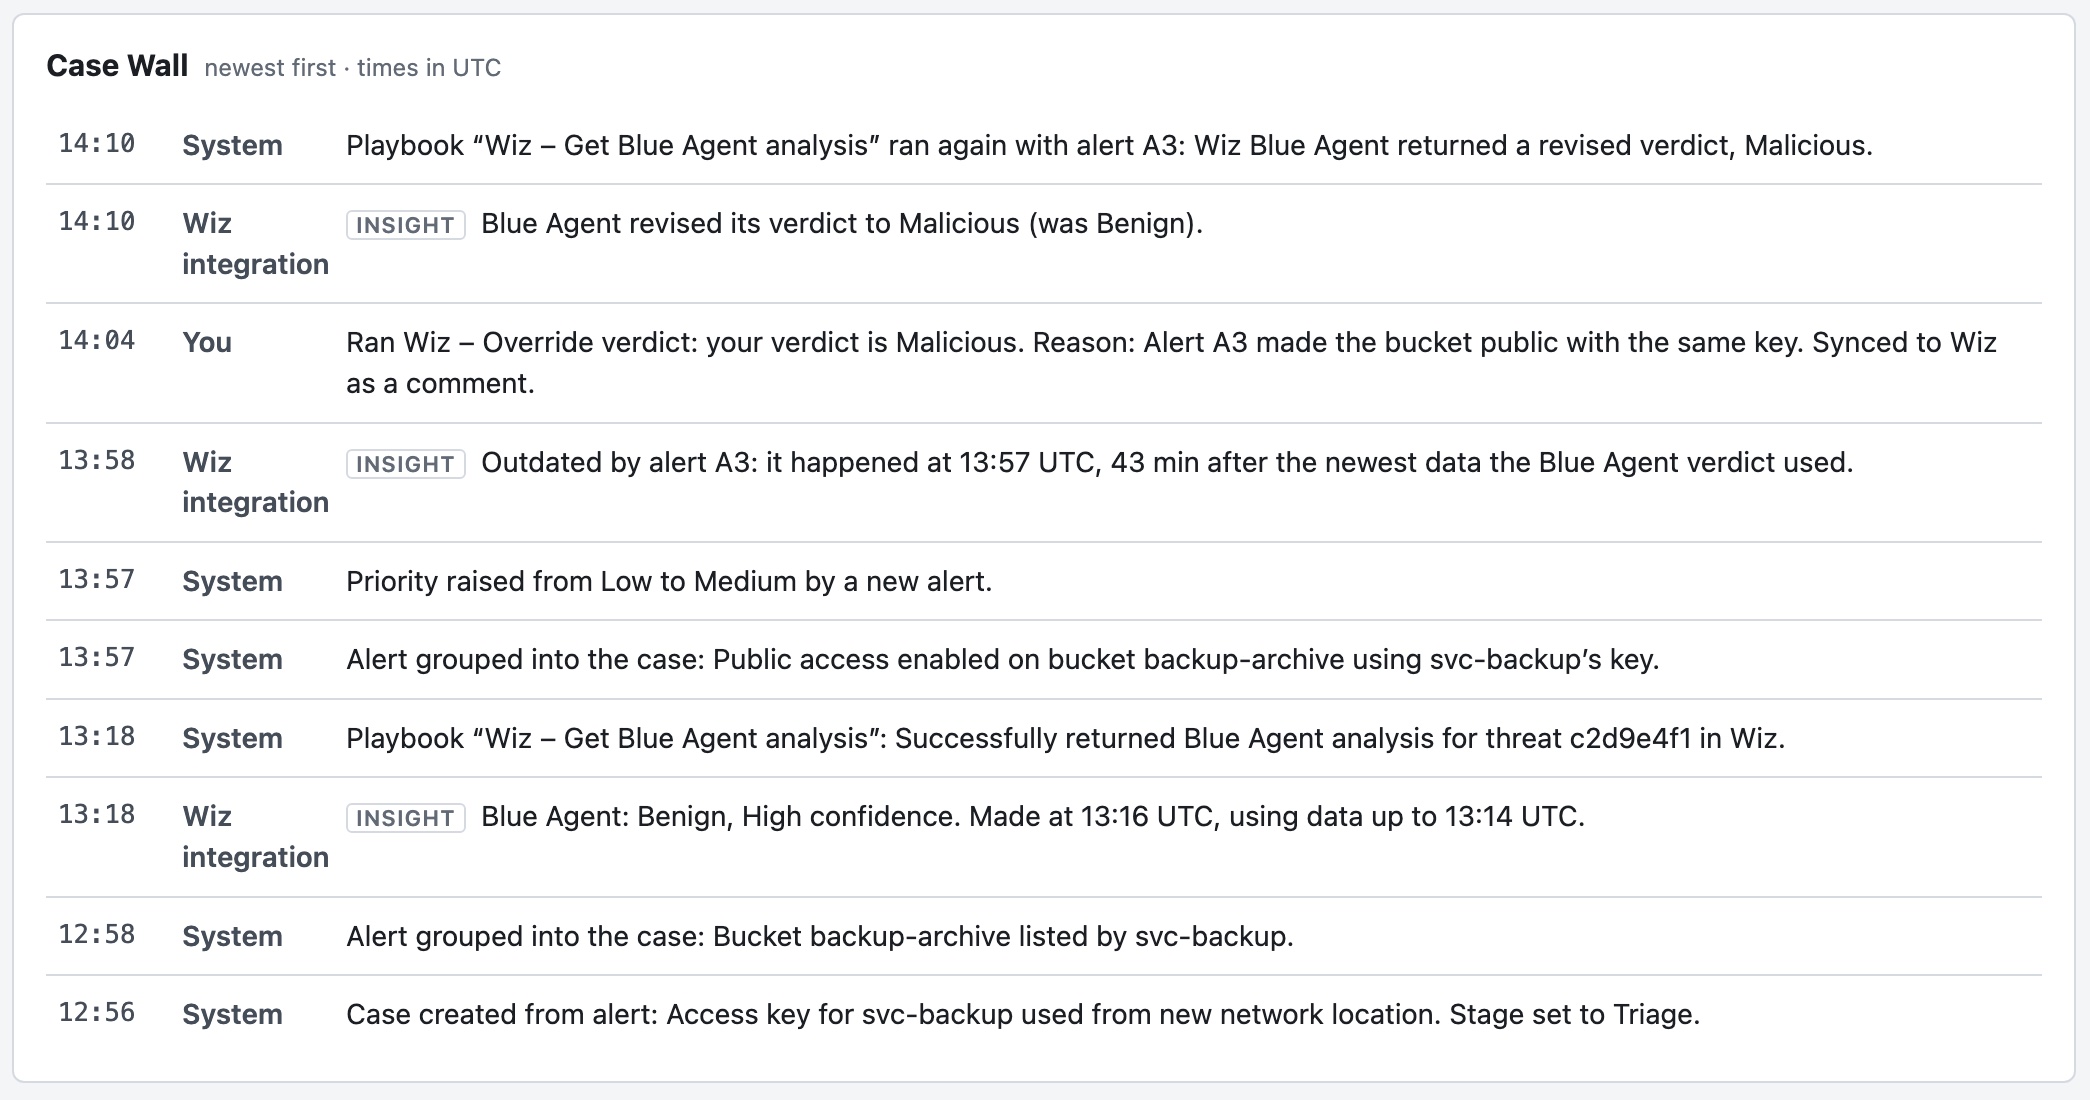
| The analyst decides | Accept is withdrawn while the verdict is outdated, so the analyst overrides it: Malicious, with a reason. Quick Actions say what they will do before they are pressed, the record goes to the Case Wall, and Undo is a Quick Action, not a sentence about undo |
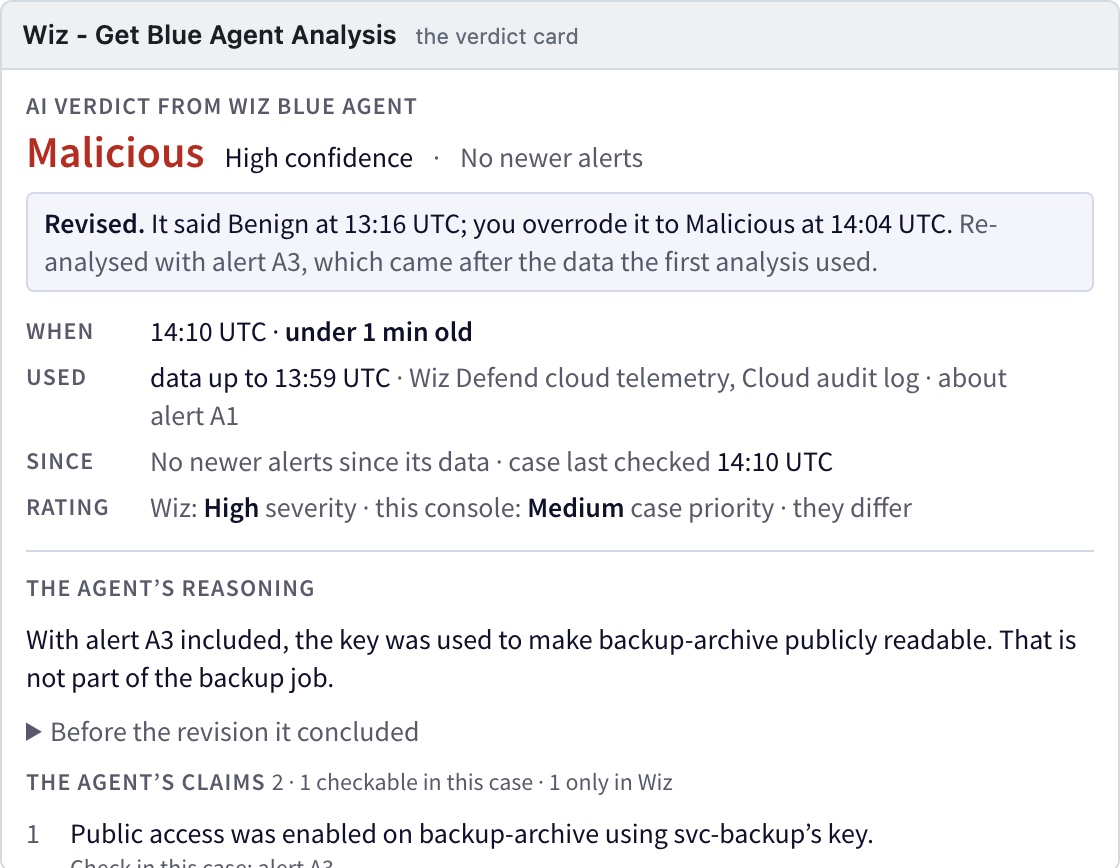
| The agent changes its mind, six minutes later | The revised result lands on the Case Wall and as an insight. On Refresh, the card shows the new verdict, severity, claims and data cut, names the analyst’s override, keeps the earlier conclusion, and the outdated warning correctly clears |
Rewritten to be read at a glance
Transcript and description
- Wiz’s launch screenshot, as this study redraws it. The dialog’s time, 2026-09-14 19:00:34, and the analysis time, 2026-07-27T15:53:10Z, are outlined and joined. “An AI verdict in Wiz’s launch screenshot: 49 days old. Nothing on screen said so.”
- Google’s widget for the action, its raw ANALYZED AT row outlined. “Google’s widget today: a raw timestamp. Nothing says if newer alerts arrived.”
- The card as published on 27 September. “My first card said it all.” Its line “As of 13:16 UTC, using data to 13:14 UTC. 54 minutes old.” is underlined, with a note: “Two times. Which one is 54 minutes old?” “Then I tripped over my own line.”
- The camera pulls back: the published card becomes one tile of 62. “So I directed 61 variations. An AI agent drew them.”
- Every tile gets a mark: its score out of 85, as a percentage, where rounds one to three recorded one; a tick where a round was judged by measurement and verdict; a pencil for the four refinements after the final; a cross for the two cut. “Screened, round by round, against seven criteria.”
- Four finalists, with their mean scores out of 85: 61.5, 66.5, 68.5 and 68.0. “Four reached the final, marked by two AI scorers. No human yet.”
- The two leaders’ first lines, enlarged. State first, 68.5: “Outdated · Benign · High confidence”. Verdict first, 68.0: “Benign · High confidence · Outdated”. “State first, or verdict first? 68.5 to 68.0. Too close to call.” “So the call was mine: verdict first.”
- The finished card at 13:50 UTC: Benign, High confidence, No newer alerts. “The finished card. Now watch the case move on.” The case clock runs; at 13:57 a new alert, A3, arrives, and at 13:58 the case check brings it to the card: “Outdated by alert A3”, Benign loses its green, and a note says the alert happened 43 min after the newest data the agent used. The age reaches “54 min old at 14:10 UTC”. Three marks: no green on a stale all-clear; the newer alert, named; how old, and when counted. “It says how old it is, and when the case moves on.”
- Before, 27 September: shows every fact it got; two times, one age; green while outdated. After, 28 September: one line answers; nine sentences, not sixteen; not shorter, 192 words. “Not fewer words. One line that answers.” Counts are the AI agent’s measure of both widget files (180 words before). No analyst has tested either card yet.
- “The agent is done. The case isn’t.” omkarux.com/verdict-card. Real widget files, synthetic case.
- Score Synthesized: a soft harmonic bed, a clock that ticks with the case’s minutes, and chimes on the moments above.
On 28 September I asked for the card to be easier to read. It read as a column of sentences: sixteen in the outdated state, with Outdated 166 px down the frame. And “As of 13:16 UTC, using data to 13:14 UTC. 54 minutes old.” gave two times and an age without saying when the age was counted.
It now reads in three layers. One line answers: the verdict, how sure the agent was, and whether the verdict still stands, in that order in every state. Labelled rows hold the facts it rests on. The agent’s reasoning and claims sit below a rule. Every phrase was then read as a newcomer would read it, and whatever could be read two ways was rewritten: the age now names its moment, “54 min old at 14:10 UTC”. Colour has one meaning. An all-clear is green only while a check says it still stands, and a warning keeps its colour, because a stale green invites closing a case that has moved on, while a stale red at worst prompts one more look.
It is not shorter: 192 words in the outdated state, against 180. It is nine sentences instead of sixteen, and the state sits on the verdict’s own line (the AI agent’s measure of both widget files, taken the same way at 560 px). Rounds one to three were scored out of 85 by the AI agent, in one pass; the later rounds were judged by measurement and verdict. Four variations reached a final, where two AI scorers, independent of each other and the same kind of reader (a human pass is still missing), put the last two directions at 68.5 and 68.0 out of 85: state first, or verdict first. The tie was mine (who decided what).
Every score the film shows
Rounds one to three, scored by the AI agent out of 85: seven criteria rated 1 to 5, three weighted 3× and four 2×. The film shows each score as a percentage of 85.
Round 1 · V00 (the published card) 47, 55% · V01 68, 80% · V02 59, 69% · V03 56, 66% · V04 52, 61% · V05 63, 74% · V06 61, 72% · V07 67, 79% · V08 49, 58% · V09 54, 64% · V10 not scored: it fails a gate by reusing the console’s tag-chip device · V11 52, 61% · V12 61, 72%
Round 2 · V13 68, 80% · V14 68, 80% · V15 67, 79% · V16 67, 79% · V17 70, 82% · V18 61, 72% · V19 66, 78% · V20 58, 68% · V21 63, 74% · V22 68, 80% · V23 71, 84% · V24 71, 84%
Round 3 · V25 74, 87% · V26 69, 81% · V27 69, 81% · V28 76, 89% · V29 69, 81% · V30 cut at 72, 85%: its outdated note said “Re-run before relying on it.”, and the card can’t know the analyst can · V31 71, 84% · V32 66, 78%
From V33 on, the film shows a ✓ rather than a number, and a ✎ on the four refinements after the final (V58 to V61).
The final · two AI scorers, each out of 85 · V49, state first: 71 and 66, mean 68.5 · V57, verdict first: 65 and 71, mean 68.0 · V48: 68 and 65, mean 66.5 · V37: 63 and 60, mean 61.5
What it refuses to do. No colour down the card’s left edge, where the host shows priority. No button inside the card: nothing the card draws can change the case, so every decision is the console’s own action. Two decorative marks on the whole card, a dot and an arrow, and each sits after words.
The card is then put through the study’s own gates, mechanically, and passes. Until 27 September that check ran only G3, legibility, and the card it passed broke G2 (what changed). It now reads the widget file itself and runs both. A check that only ever passes proves nothing, so it runs on Option 0 too, and names its failures there.
A verdict produced by one product is read inside another, by an analyst who owes their attention to the case, not to the agent. The agent is a guest there, even when one company owns both. These are the obligations that come with being one, each traced to a row in the count or a criterion in section 01. The list itself is on the case study page.
A rule that only fits one pairing isn’t portable, so an AI agent checked all eight on paper against a different guest in a different kind of host: Dropzone AI writing into ServiceNow, where the AI polls the ticket queue, investigates in its own console, and posts its result back as a comment. By its check, seven of the eight apply as written. Rule 5 needed rewording, because in a ticketing tool most evidence lives outside the host, so “in the host’s own objects” became “and say where” — which the card already does. And rule 7 flipped: there, a comment is the only channel, so the text entry isn’t the fallback — it is the card. That’s why the freshness line is the first thing I’d ship. This tested whether the rules apply, not whether Dropzone follows them.
No analyst has used this. n = 0. The design rules stand as argued, not as tested.
The protocol is written — consent, three tasks, time to first correct action, five debrief questions, a scoring sheet. The prototype scores its own sessions and exports them, and a self-serve link needs no calendar and no facilitator. That is the next thing that happens, and whatever n it reaches gets printed first, in the findings.
What would make this wrong
Written before any data. Changes are dated, and made before any data.
- If analysts find the verdict just as fast with Google’s widget, or no widget at all, the count overstated the problem and the card is solving something smaller than I claimed. Adjusted 27 Sep, still before any data: the fair comparison is now Google’s own widget.
- If they catch the stale verdict without the card, freshness belongs in the host’s timeline, not in a guest’s widget, and rule 2 is aimed at the wrong surface.
- If the low-confidence card makes them slower without making them more accurate, withdrawing the recommendation is friction rather than safety, and it goes.
- If consoles start giving a guest’s verdict the treatment they already give their own AI — the landing view, a date, a history — the card becomes the host’s job. That would be the right outcome, and this study would have been an argument for it.
What I’d ship first
Step 1, then step 2: the freshness line, then the claim-level checkability. The freshness line is the cheapest, and it works in the action’s own Case Wall line as well as in a widget; checkable claims need the agent’s result to carry them. Between them they carry the two failures the audit found: a verdict whose age nothing on screen states, and a claim you cannot follow.
What I’d cut
The preview-drawer density, until someone confirms a ready-made widget renders in that drawer at all. The docs do not say, and I could not check without a tenant. It is drawn because rule 1 demands it, not because it is known to be buildable.
What only a live console can settle
Some of how the card is installed can’t be checked without a tenant, such as whether a widget redraws by itself when a new result arrives, and which result it reads when an action has run for two alerts. The docs don’t say, so each one is printed rather than guessed.
What breaks at scale
Claim-level checkability assumes the agent’s claims map onto objects the host holds. On a case with one alert that is easy. On a case at the host’s own documented ceiling, “checkable in this case” stops being one click and starts being a search, and the card would need to say which.
And the card only sees what lands in its case. The host groups a new alert into an open case when the two share a single entity, inside a window its admin sets. It opens a separate case if the admin’s timeframe, from half an hour to a day, is shorter than the gap between the alerts, or if the case is already closed, because grouping never reopens one. A rule that groups by the source’s own identifier uses no timeframe at all. That second path is the worst version of this whole problem: the analyst trusts the verdict and closes the case, and the evidence against it arrives somewhere else. A card inside one case cannot see that. Catching it needs something that looks across cases, and this study did not design it.
A clean narrative is not the same as a tidy process. The prose above reads forward; this is the order things actually happened in, and who decided each one.
The hypothesis came first, written on 17 September before the audit. H1: the meaning of the icons and badges in the case view is discoverable only in the docs. H2: an external agent’s verdict has no designed home in the case. The audit found H1 too generous to the docs, because some marks aren’t explained there either. H2 held in the public screenshots, and on 27 September it was partly refuted: Google’s content hub ships a widget for this action, a home an admin can add.
| Date | Decided by | Decision | What it changed |
|---|---|---|---|
| 17 Sep | Omkar | Write the hypothesis before gathering the evidence | The audit could refute it, and partly did |
| 17 Sep | AI, reviewed | Publish the counting rules with the count | A count that can be disputed, and re-run by script |
| 17 Sep | AI, reviewed | Propose seven criteria at 18:17 IST, before any option exists | Confirmed as six on 18 Sep, after all six options existed |
| 17 Sep | Omkar | Judge directions to develop, not finished candidates. Scope: guest only | Findings about the host stay findings, never proposals |
| 18 Sep | Omkar | Six criteria, not seven: legible with no admin setup becomes a briefed requirement | A criterion every option satisfies cannot separate them |
| 22 Sep | AI, reviewed | Refuse to re-point the audit at the revamped view | No screenshots there; a count would be assertion |
| 23 Sep | AI, reviewed | Uphold the gate failure against Option 0 | The version generated from the original ask came last |
| 23 Sep | Omkar | Mix the top options rather than crown one | The answer is a hybrid, and each part names the option it came from |
| 23 Sep | Omkar | Add three things no option drew | Low confidence withdraws Accept, undo is a control, and the verdict can be revised after the analyst acts |
| 27 Sep | Omkar | Check the card against the real product before rebuilding it | Found Google’s own widget for the action, the acquisition, and the card’s own G2 failure |
| 27 Sep | Omkar | Rebuild the card as the widget file it would ship as | Decisions moved to Quick Actions, and the check now runs both gates |
| 27 Sep | Omkar | Reframe around two products, not two vendors | A new title: the agent is done, the case isn’t |
| 27 Sep | AI, reviewed | Show Google’s widget running its own code, not a drawing of it | “Today” is the real thing, checkable by anyone |
| 27 Sep | Omkar | Withdraw Accept while the verdict is outdated, and fix what the card says now rather than later | Accept only while the verdict is current and confident. The card says what the agent read, what it is about, and when the case was checked |
| 28 Sep | Omkar | Make the card easier to read, with every variation judged against criteria | Sixty-one variations of the published card, each drawn from its real data in every state; the last rounds in the host’s three themes too |
| 28 Sep | AI, reviewed | Propose seven readability criteria before the first variation is drawn | Confirmed by me after the first round was drawn, before any was scored |
| 28 Sep | Omkar | Look again for emphasis, then read every word as a newcomer would | Secondary facts went quiet, and every phrase that could be read two ways was rewritten |
| 28 Sep | AI, reviewed | Green only for an all-clear that still stands; a warning keeps its colour | A stale all-clear no longer looks safe, and no risk loses its colour |
| 28 Sep | Omkar | Break the scorers’ tie: the verdict first, in one order in every state | The state is read second, and the line never changes order |
All six options were machine-generated, and two AI scorers scored them; the margins above are theirs. An AI agent also ran the count, drafted the criteria, the gates and the eight rules, and built the widget, the prototype and their tests. What is mine is the problem, the scope, the cut from seven criteria to six, the call to mix the top options rather than crown one, the decision to add three things no option drew, the call to check the card against the real product before rebuilding it, withdrawing Accept while the verdict is outdated, and the redesign for reading: asking for it, the word-by-word read, and the call between its last two directions. The page says which is which because concealing it is the actual red flag.
Everything corrected or changed since these pages were first published on 23 September, newest first. Each claim was fixed where it stood; the notes that used to sit beside them are gathered here.
- 29 Sep · A film of the redesign. “Rewritten to be read at a glance” now opens with a 62-second film of how the card got there, with a transcript. The two scorers’ marks for all four finalists, and every screening score the film shows, are listed beneath it. The film.
- 28 Sep · The card, rewritten to be read at a glance. Its wording changed, and every quote of it on these pages changed with it: “As of 13:16 UTC, using data to 13:14 UTC. 54 minutes old.” is now “13:16 UTC · 54 min old at 14:10 UTC” and “data up to 13:14 UTC”, and “Outdated.” is now “Outdated by alert A3”. What changed, and why.
- 27 Sep · Accept, and what the card says. Accept is now withdrawn while the verdict is outdated, not only at low confidence. The card now says what the agent read, which alerts the verdict is about, and when the case was last checked. Outdated compares when an alert’s events happened with the data cut-off, not when the alert joined the case. A revision names the analyst’s decision.
- 27 Sep · Who proposed the three additions. This page called them “the parts of this card a machine did not propose”. The scorers flagged each of them, and an AI agent proposed adding them. The decision to add them was mine, and the page now says only that.
- 27 Sep · What the scorers found. This page said both scorers found “the same hole, independently and in near-identical words”: low confidence changes what almost no card offers, and none withdraws the action. One scorer found that no option restrains the act; the other credited R5 with withdrawing its recommendation line. The page now reports each, and the addition is named for what no option did: withdrawing Accept.
- 27 Sep · What syncs in real time. The case study page said status, severity and comments sync in real time. That is Wiz’s description. In the integration’s sync job, which an admin sets up, status and comments move both ways and severity one way.
- 27 Sep · Microsoft’s rule. The console page called Microsoft’s “didn’t change significantly” check this card’s Outdated state, already shipping, and the card a request for parity. Microsoft uses it to decide whether to redisplay a cached summary. A date is parity; saying Outdated on screen is new.
- 27 Sep · The 49 days. A caption said the gap is 49 days “however the zone-less fetch time is read”. It is 49 days if the fetch time is UTC, and within a day of that in any time zone.
- 27 Sep · A date in the log. The choice to judge directions rather than finished candidates, with the scope limited to the guest, was dated 18 September. It was made on 17 September.
- 27 Sep · How severity syncs. This page said status and severity sync both ways. In the integration’s sync job, status syncs both ways; severity moves only from Wiz, and only upward.
- 27 Sep · Two products, not two vendors. The pages called Wiz and Google two vendors, under the title “One vendor’s verdict, another vendor’s case”. Google completed its acquisition of Wiz on 11 March 2026, before this study began. The finding is about two products meeting in one case, and it stands. The title is now “The agent is done. The case isn’t.”
- 27 Sep · Today’s baseline. The pages compared the card with raw data only. Google’s content hub ships a ready-made widget for this action, and the pages now show it running its own code. It partly refutes H2.
- 27 Sep · The card’s own buttons. The card drew Accept, Override and Undo inside itself, with links that steered the console to an alert. An HTML widget displays, and its one documented exception, an approval link, only answers a playbook step that is waiting. That is gate G2, the rule Option 0 failed, and the script that checked the card ran only G3. The card is now the widget file it would ship as: its decisions are Quick Actions, their record is the Case Wall, and the script runs both gates.
- 27 Sep · Who writes ready-made widgets. The case study page said a ready-made widget tied to your integration’s actions “is made by Google, not by you”. Partners write them too, and Google verifies and publishes them.
- 27 Sep · When the console changed. The console page said Google shipped the revamped view on 18 September, the day after the audit, and called that the study’s strongest evidence. The revamp entered public preview on 26 July; 18 September only made its side panels resizable. Nothing affecting the count changed after the audit.
- 25 Sep · When the criteria were set. This page said the criteria were “committed 90 minutes before the first option”. Seven were proposed then, and the six were confirmed only after all six options existed. The claims that rested on it were taken down, as was the claim that the counting rules were published before the count: they were committed together.
- 25 Sep · Who made Option 0. This page said Option 0 was mine, “the one I built myself”. It was generated by a model, like the other five.