How it was scored
Six interface directions an agent drew against the model, the rubric that scored them, what three evaluations disagreed about, and why the corrected table is a tie. Then the visual round, and what four checks found.
Contents
Six credible options is a worse position than two. With two you can argue. With six you pick the prettiest and construct the reason afterwards.
I did not draw the six. I gave a Figma agent the state model — field types, legal methods, no-op rules — and asked for six distinct directions against it. What is mine is the model underneath, the rubric that follows, and the judgement about which one is right.
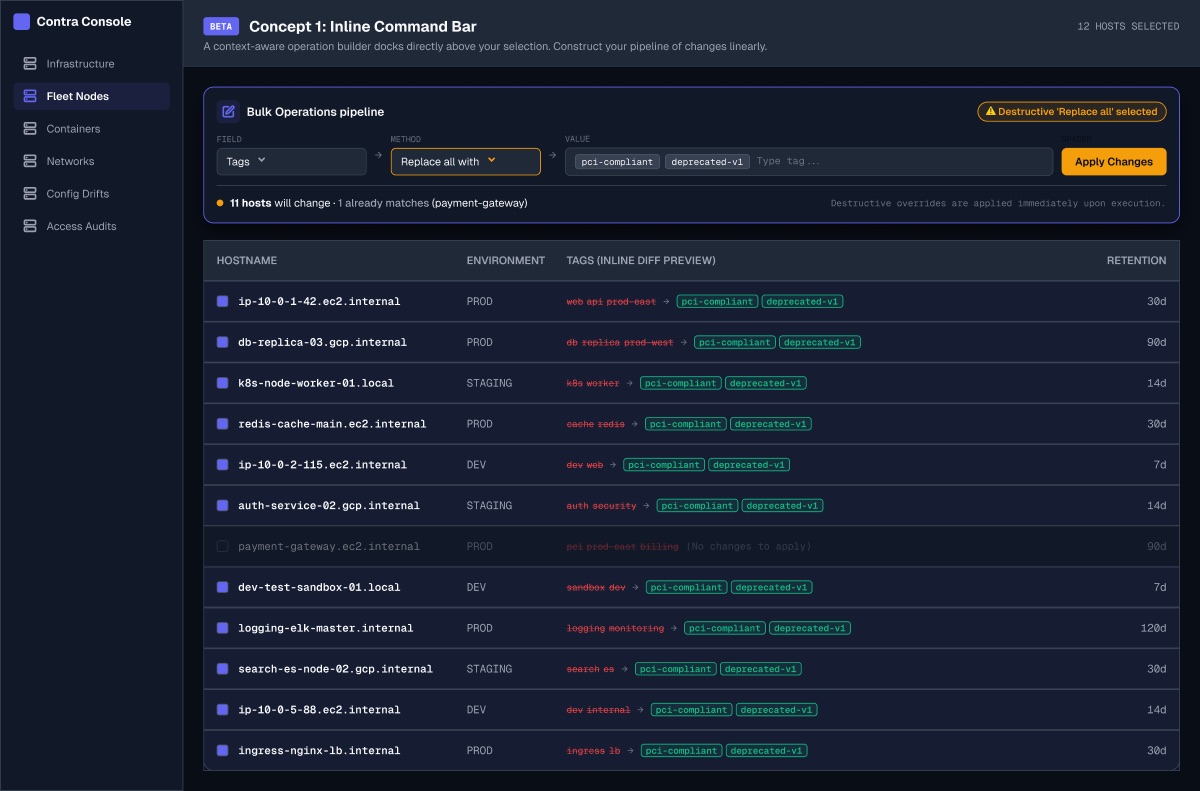
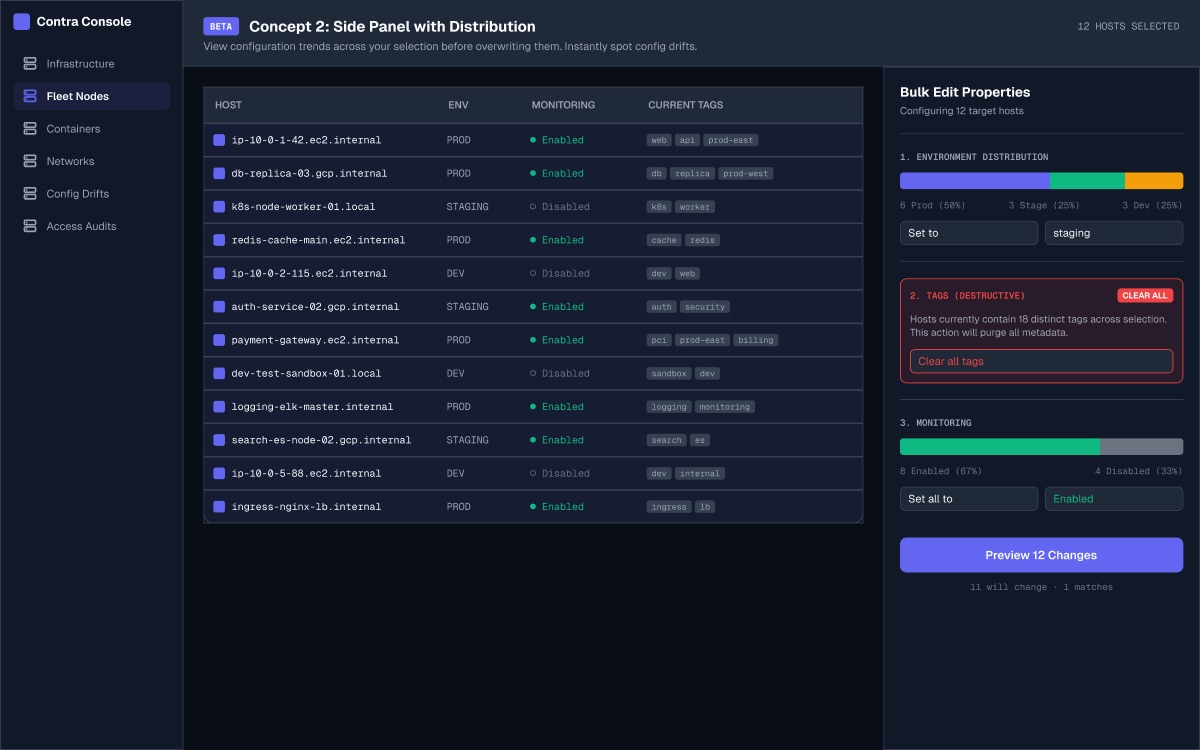
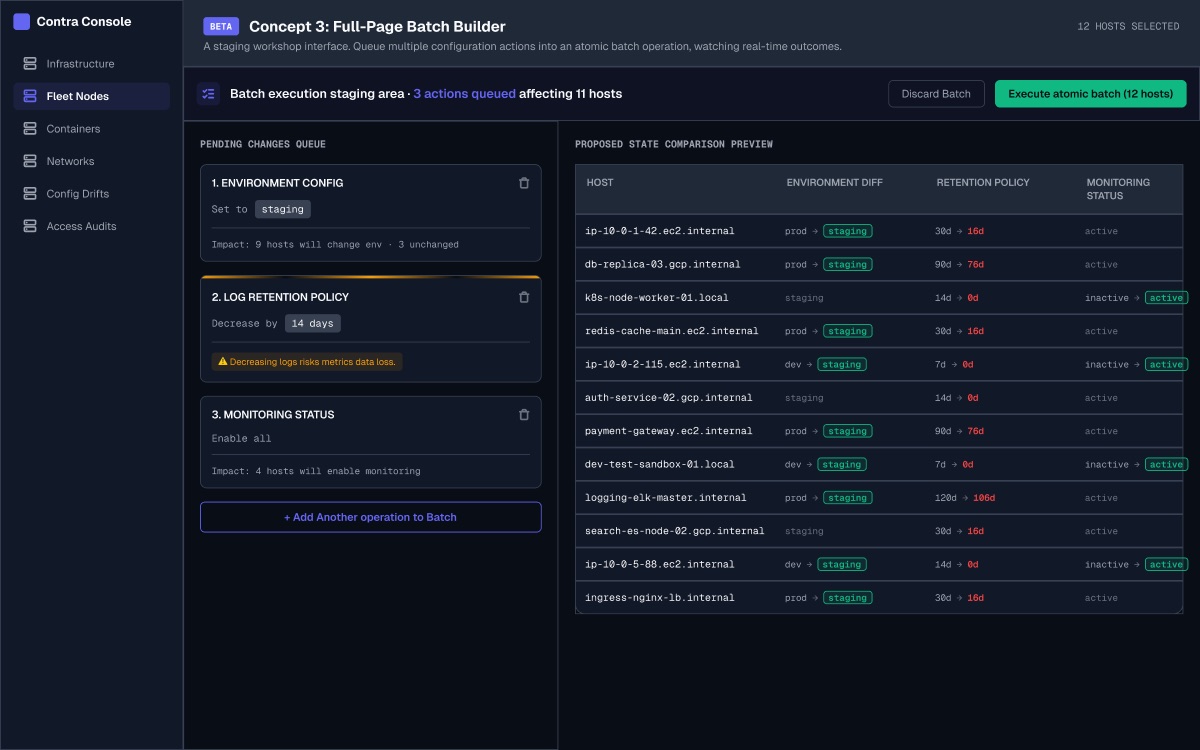
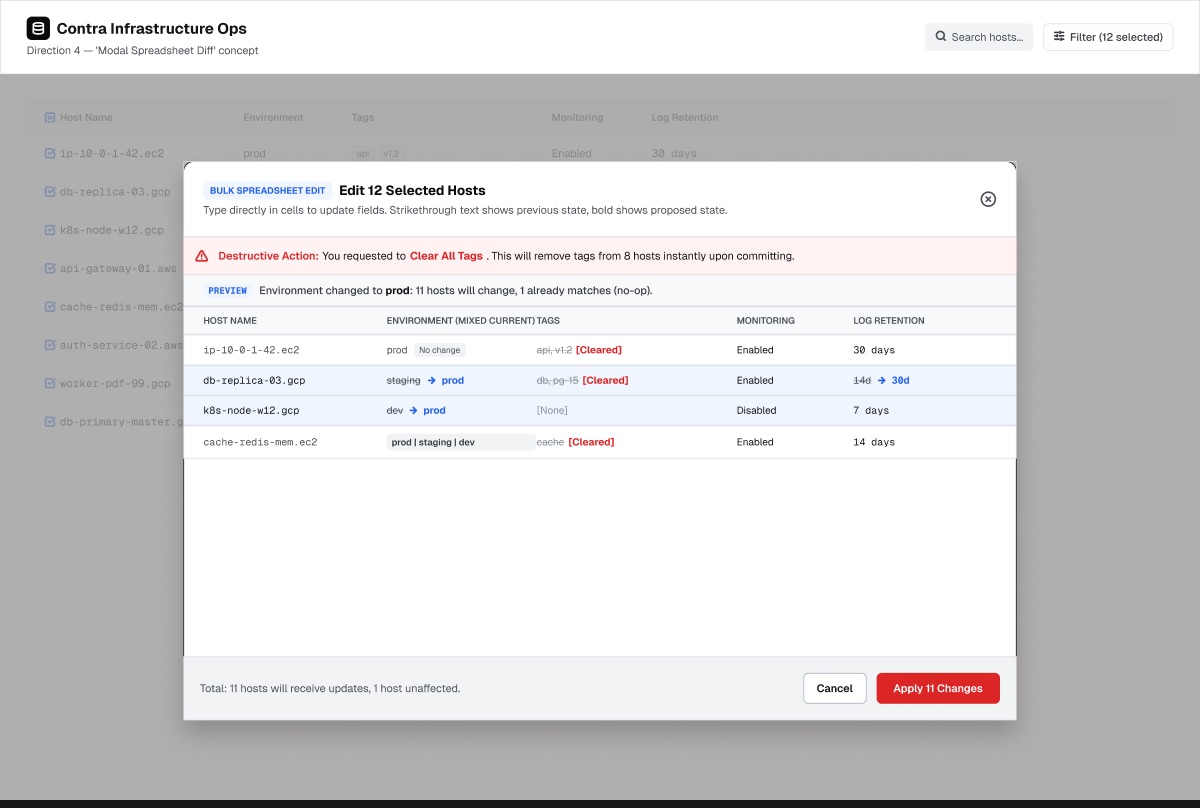
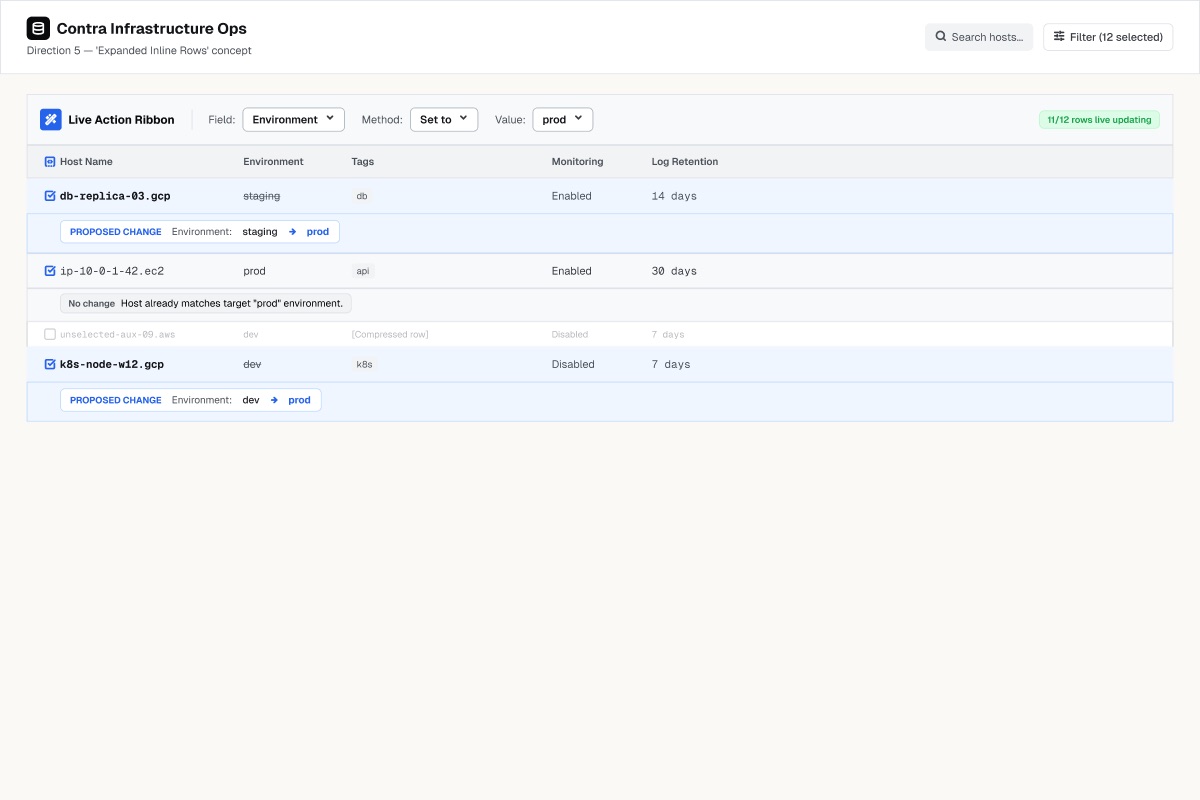
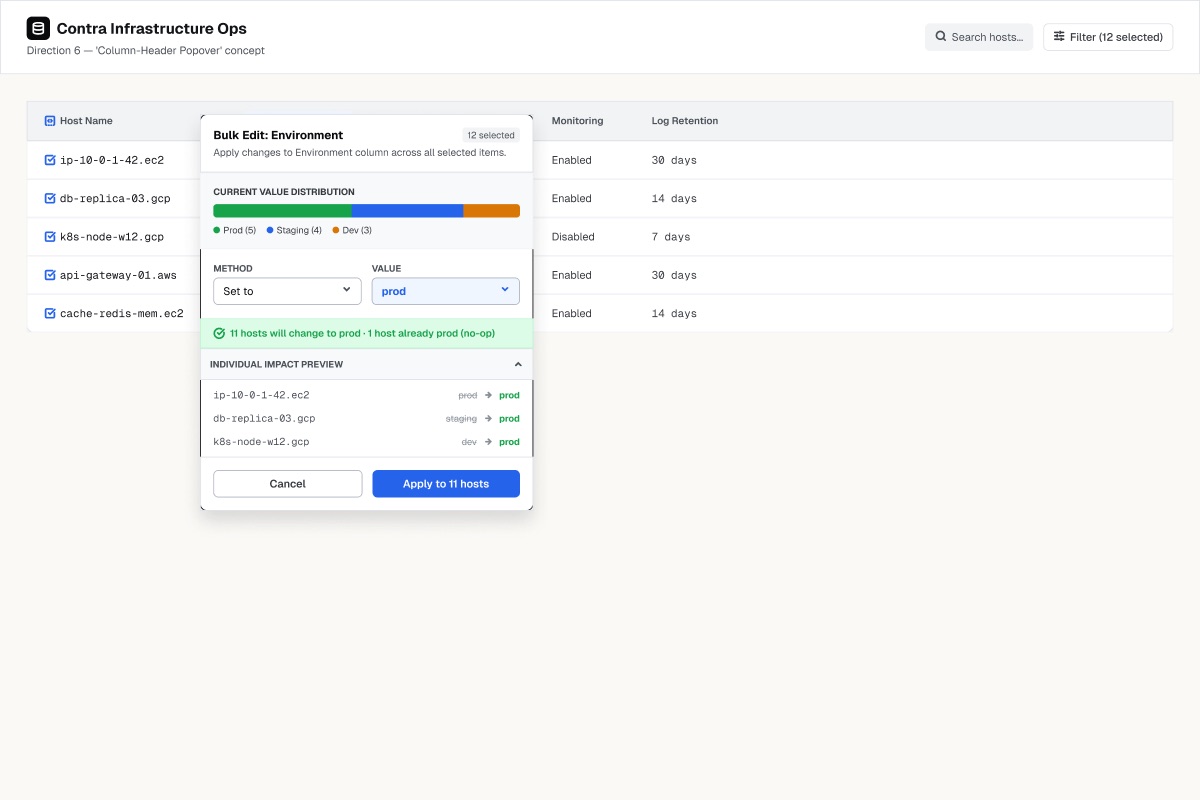
All six are plausible. That is the problem.
What I left out of the rubric
Sixteen criteria, drawn from Nielsen Norman’s heuristics, the seven hard cases, and the fact that it has to ship as a web component. The useful part is the exclusions. Three of Nielsen’s ten were dropped because they could not discriminate between six concepts that share a vocabulary, and one — aesthetic and minimalist design — was kept but rewritten, because scored directly it is taste. It became two falsifiable questions: does it hold at 1,000 rows, and does a screenshot explain itself. The decision table, heuristic by heuristic, is in why-these-criteria.md →
Four more things were deliberately not measured: visual polish (four of six were rendered by the same agent in one pass, so render quality is noise), novelty, accessibility beyond keyboard (identical work for all six, so it cannot discriminate), and click count as a headline number.
The fewest-clicks option here is also one of the least honest. Optimising clicks on a destructive, multiplied, irreversible operation is optimising the wrong thing.
Honesty and error prevention carry three times the weight of everything else, because a dishonest interface that is faster is not better, it is worse — it accelerates a wrong action across every selected item at once.
| Category | 1inline bar | 2side panel | 3batch builder | 4modal | 5inline rows | 6popover |
|---|---|---|---|---|---|---|
| Honesty ×3 | 18 | 18 | 18 | 21 | 21 | 21 |
| Error prevention ×3 | 18 | 12 | 24 | 18 | 9 | 12 |
| Cognitive load ×2 | 16 | 16 | 14 | 10 | 14 | 14 |
| Efficiency ×2 | 10 | 12 | 10 | 8 | 10 | 10 |
| Craft fitness ×2 | 16 | 16 | 12 | 10 | 12 | 16 |
| Total of 117 | 78 | 74 | 78 | 67 | 66 | 73 |
Two criteria did the separating. Locality — how far the control sits from the data it changes: direction 1 renders the diff in the real row, so there is no moment where you are reviewing a representation of your change rather than the change; direction 4 puts the data behind the thing editing it, greyed out and unreadable. And legibility at scale — does it hold at 1,000 rows, not 12.
Correction. Direction 1 does not deserve a 3 here, and I only saw why when I started planning the build. Its layout survives 200 rows; its review does not. A long scroll is not verification, and large selections are exactly where a mistake costs most. I had scored “the layout does not break” and written it down as “this still works”. It is a 2, and the gap it opens is addressed on the main page.
Directions 1 and 3 tie at 78 of 117, so there is no winner.
Corrected 25 Sep 2026. This section said direction 1 won at 80, with direction 3 second at 78. The correction above had never been applied to the table. Applied, direction 1 scores 78 and ties direction 3. The build started from direction 1, on the uncorrected result.
One disclosure, because it matters: I had recommended combining directions 1 and 2 before building the rubric, and the rubric then ranked them first and third.
I ran a second evaluator — a reusable one I had published to my design team — over the same six. It ranked the modal spreadsheet first. My rubric had put it fifth of six. The cause was one line in the evaluator’s own decision record:
“I scored what I could verify in the design, not what the brief promises.”
The evaluator, explaining its own scoring ruleMine did the opposite — it credited a shape for what it could naturally hold, whether or not the frame showed it. On the specific point it was right and I was careless: the modal drew the best destructive warning in the set, naming the action, the host count and the irreversibility, and I had noted only that a banner existed.
But the two rules answer different questions. Which of these should we ship? scores what is demonstrated. Which of these should we develop? scores what the structure can hold. These were round-one concepts generated to be developed — and neither evaluation had been told which question it was answering. Each silently picked, and the pick decided the winner.
They did not disagree about the designs. They disagreed about what counts as evidence — and nobody had asked.
So I fixed the instrument rather than the answer: state the question up front, score every option twice and publish where the two passes disagree, generate criteria for capabilities no option has, and enforce the close-call gate that already existed on paper. The re-run inverted the ranking and converged with my rubric. That is evidence, not proof — both could still share a blind spot neither has been asked about.
Two criteria scored identically across all six: every concept made current state visible, and every one was framework-independent. A criterion that never separates anything is not a criterion, it is a precondition. Those should have been an entry filter.
Three others were also nearly flat, and they mean the reverse. Scope honesty, partial failure and keyboard operation scored 1 or 0 almost everywhere. Same statistical signature — a column of matching numbers — and the opposite conclusion.
Flat because everyone passes is a wasted criterion. Flat because everyone fails is the most valuable thing the rubric produced.
Six independently generated directions all missed the same three things. None handles select-all beyond the current page — the difference between “12 selected” and “1,847 matching your filter” is the difference between a routine edit and an incident. None shows partial failure: nine of twelve succeeded, and there is nowhere for the three to go. None shows a keyboard path, for a tool someone runs many times a day.
Those three gaps became the build list. All three are in the component on the main page — scope beyond the current page, partial failure with a retry scoped to what failed, and Esc to back out of any state except a commit in flight. The keyboard path was the last one, and it only got built because an end-to-end review caught this sentence claiming it already had been.
Planning the build surfaced a problem no evaluation had caught: the inline diff is only reviewable while the selection is small. The fix, grouping by transition, is on the main page. This is what it did to the scoring.
It dissolved the decision I thought I was making
Directions 1 and 2 had looked like a trade: per-item impact against aggregate distribution, one or the other. Grouping shows they are the same object seen at two moments. The distribution is the state before the operation; the grouped diff is the state after. summarise() gives the first and groupByTransition() the second, and both are in the model.
So the distribution bar is not a consolation prize grafted onto direction 1. At scale it becomes the index into the diff.
What this cost: a scoring error that survived my own rubric, a full evaluation, and a corrected re-run of that evaluation — three passes, none of which asked what happens at two hundred rows. It was caught by trying to build the thing. That is not an argument against evaluating; it is a reminder of what evaluation cannot reach.
The visual round. Three directions of mine, five from a Figma agent, against one specimen — the same 200 hosts, the same clamp. All five agents chose an ordinal ramp for an ordered scale, which made my Instrument, with its five unrelated hues, the outlier. It was wrong. So was the component: it had been drawing that distribution bar in six unrelated hues the whole time, and stayed that way through my first pass at building direction 1 — a polish theme that changed corner radius while the losing direction’s colour logic ran underneath. All five also marked when the system had intervened on a clamp. I had managed that in one of three.
Contrast was a hard gate, not a scored criterion: a direction whose stated mechanism fails its own measurement is making a false claim, not an incomplete one. The gate eliminated all eight. So it could not select, and became a better question — is the failure in the palette, or in the mechanism? Only Grid’s was in the mechanism: its amber row exists to make the row glow, and measures 1.04:1.
Flow won at 74.7%, and building it showed the round’s limits. Its arrow was scored on one specimen — a numeric decrease, with a clamp, three groups. Three things about the real component were not in that frame. A clamp needs a numeric field and a relative method, so it is impossible on tags, booleans and selects. Real group sets are often two rows, where reading two numbers beats comparing two arrow lengths. And every row opens with a disclosure caret the static frames did not have, so the arrow landed right beside it — a control glyph beside a data glyph, both pointing.
So the mark appears only where there is something to mark: on the clamped row, after the label — beside the thing it qualifies rather than the thing you click. What survives is what a number cannot do live: drag the operand from 7d to 14d and the clamped group grows while the distribution above it holds still, because it did not change. Every operation that cannot clamp gets the width back.
The row that says nothing will happen used to be grey on grey at 3.40:1. It is now body ink at 16.67:1. That was not a darker grey: the grey was repeating what the missing arrow already said, and the repetition is what broke it. Deleting it fixed both.
All eight directions, each with its own reasons and its stated cost, are on one page: see the eight → — mine live, the agent’s as the frames they came back as. The scoring documents are in the repo too, because a rubric you cannot read is just an assertion with a number on it: round 1, six interface concepts → · what came back → · round 2, eight directions scored →
Then someone read the case study, used the component on it, and found three more in an afternoon: a select that displayed a value the state did not hold, an Add another operation button that stopped working once you removed an operation, and per-operation previews that had never been built at all. That narrows the claim rather than overturning it. An instrument finds what it was pointed at, and all four of these had been pointed at the evaluation. Nothing had been pointed at the interface after the evaluation was over, so the person using it got there first.